Measure AI Project ROI Without Fooling Yourself
14 September 2026
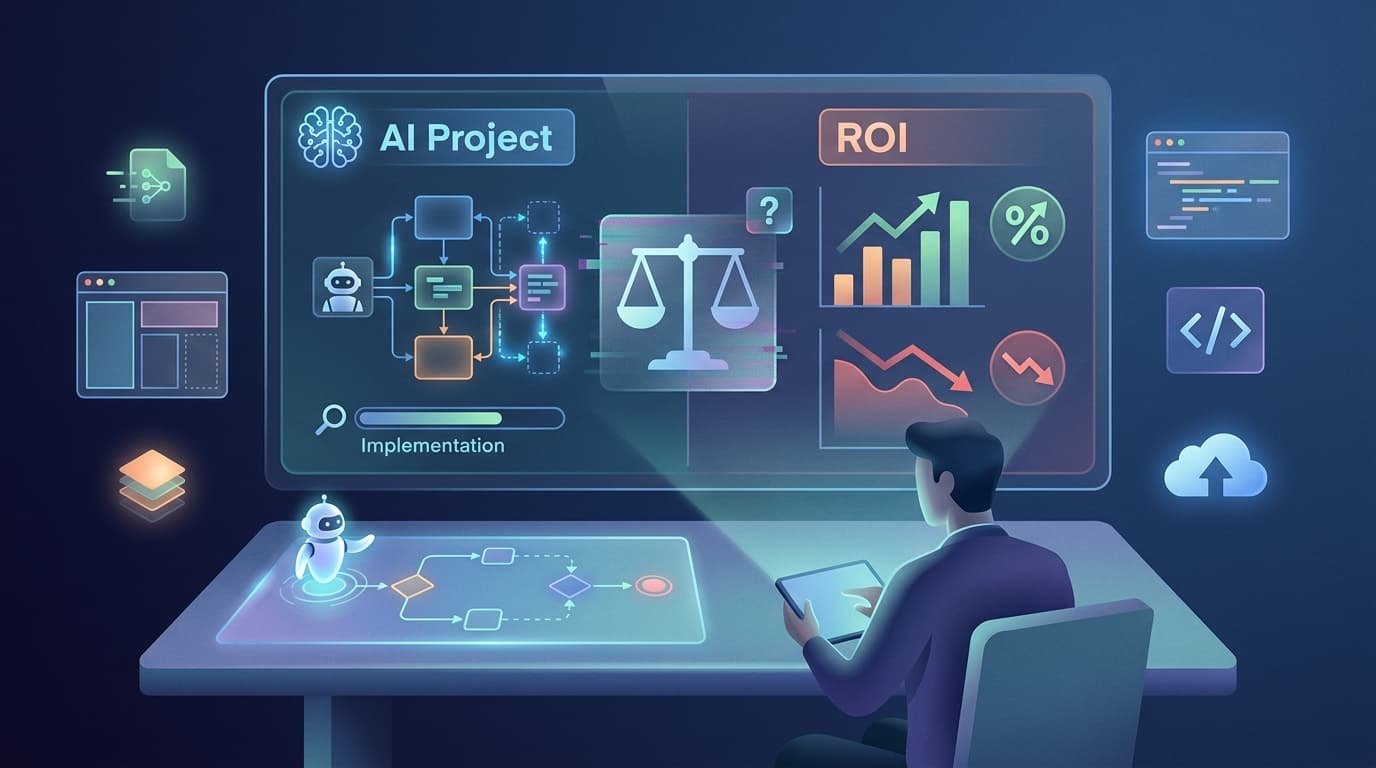
An AI pilot can look successful long before it creates business value. A team sees polished answers, a demonstration runs quickly, and someone estimates that it will save hundreds of hours. Six months later, the workflow still has the same bottleneck, adoption is uneven, and the monthly model bill has become a surprise. The problem is not that return on investment is impossible to measure. It is that too many AI projects measure activity, not outcomes.
A useful AI project ROI framework connects the technology to a specific operational decision: what work changes, for whom, at what cost, and how will we know the change is genuinely better? It should include financial value, but it should also account for quality, risk, adoption, and the ongoing cost of running the system.
This article gives business leaders a practical way to measure AI project ROI without inventing certainty. It is designed for custom AI, workflow automation, and AI-agent initiatives where value depends on how well the solution fits the real work.
Why Common AI ROI Calculations Mislead
The simplest AI business case multiplies estimated minutes saved by an employee cost. That can be a useful starting point, but it becomes misleading when treated as a result. Saving ten minutes on a task does not automatically produce €10 of value if the task still waits in the same queue, the saved time is spent checking errors, or nobody changes capacity plans.
Several blind spots recur:
- Potential savings are counted as realised savings. A model may draft a response faster, but the business may keep the same process and headcount.
- Quality costs disappear. Rework, incorrect recommendations, compliance reviews, and customer dissatisfaction can erase a productivity gain.
- Build cost is mistaken for total cost. Integration, monitoring, model usage, support, security, and ongoing refinement are part of the investment.
- The baseline is weak. Without measuring the current process, a team cannot distinguish a genuine improvement from normal variation.
- Adoption is assumed. A technically capable tool that users bypass has no operational ROI.
The answer is not to wait for perfect data. It is to make assumptions explicit and verify them in stages. That begins with a workflow, not a model. If the team has not mapped how work moves today, use the discovery approach in our guide to designing software around real workflows before estimating what AI will change.
The Five-Part AI ROI Framework
A credible measurement plan has five connected parts. Together they support a decision to start, scale, change direction, or stop.
1. Define the job and the decision boundary
Describe one bounded job in plain language. “Improve customer service with AI” is too broad. “Classify incoming support requests, prepare a draft response for routine queries, and route exceptions to a specialist” is measurable.
For that job, identify the trigger, the desired outcome, the people involved, the systems touched, and the actions an AI system may or may not take. A narrow boundary makes user-centric design possible: the solution can be built around what the person actually needs at that point in their work.
Then set a decision rule before the pilot begins. For example: scale only if the assisted workflow reduces median handling time by 25%, preserves or improves quality, reaches 70% adoption among the intended users, and stays below a defined monthly cost. A pre-agreed rule is the best defence against both hype and unfair scepticism.
2. Establish a baseline with operational measures
Measure the current state for long enough to capture normal variation. Use metrics that connect directly to the job:
- Time to complete a task, including waiting and rework where possible.
- Error, escalation, and correction rates.
- Throughput per person or team.
- Customer outcomes such as resolution time, repeat contacts, or satisfaction.
- Compliance checks, exceptions, and audit findings.
- Employee effort and confidence, gathered through short structured feedback.
Do not use a single average if it hides the experience of difficult cases. Look at medians and segments. An AI assistant that helps routine cases but harms complex ones may be worthwhile, but only if the workflow routes complexity safely and the team understands the trade-off.
3. Model benefits in three categories
Hard financial benefits are directly visible in the accounts: reduced contractor spend, avoided software licences, lower processing cost, fewer refunds, or revenue recovered from faster follow-up. Be conservative and record the evidence source.
Capacity benefits are time or throughput gains. Count them as value only when there is a clear plan to use the released capacity, such as handling more customers without hiring, clearing a backlog, or moving specialists to higher-value work. A 15-hour weekly saving is useful, but it is not automatically €15,000 of cash.
Quality and risk benefits include fewer errors, more consistent decisions, better service, and a stronger audit trail. These can be material, especially in regulated or customer-facing operations, but they need proxy measures. For example, track avoided rework, decline in repeat contacts, or the value of exceptions caught before they reach a customer.
This broader view is why AI should be treated as a business system, not a chat interface. For a practical sense of the recurring operational costs that belong in the calculation, see the real cost of running an AI agent in production.
4. Calculate total cost of ownership honestly
Include the full cost over a defined period, commonly 12 months:
- Discovery, design, development, and integration.
- Data preparation, permissions, and security controls.
- Model, hosting, and third-party API usage.
- Human review and exception handling.
- Monitoring, evaluations, support, and improvement work.
- Change management, training, and process documentation.
For illustration, imagine an invoice-triage assistant costs €36,000 to implement and €1,500 per month to operate. Its first-year cost is €54,000. If it enables a team to absorb €72,000 of additional annual workload without extra recruitment and avoids €12,000 of correction costs, the first-year net benefit is €30,000. That is a useful result, but only if the workload and correction figures are observed rather than assumed.
Avoid chasing a single percentage too early. Payback period, net benefit, and sensitivity ranges are often clearer for decision-makers. If model usage might double with volume, show that downside case. Robust, scalable architecture means the team understands how cost behaves before demand arrives.
5. Measure quality, adoption, and safety continuously
AI changes over time. Prompts change, data changes, providers update models, and users learn workarounds. A one-time pilot score cannot prove ongoing ROI.
Set up a small dashboard that combines business outcomes with technical evidence: task volume, cost per completed case, quality sample scores, exceptions, escalation rate, active-user adoption, and model performance. Keep representative examples available for review, particularly where customers, money, or regulated data are involved.
This is where AI evaluation becomes part of financial governance. An agent that is cheaper but produces more incorrect output is not an optimisation. Testing on real cases, monitoring regressions, and retaining a human route for consequential decisions protect both customers and the business case.
What a Good Pilot Looks Like
A strong pilot is deliberately small and designed to answer a decision. Consider a service business that receives 800 incoming requests each month. It chooses one category of routine requests, establishes a four-week baseline, and deploys an assistant that drafts replies while staff approve every response.
The team compares assisted and unassisted cases. It finds that median handling time falls from twelve minutes to seven, quality sampling remains stable, and 78% of eligible staff use the assistant. However, requests involving account changes create too many corrections, so those remain outside the automation boundary. The pilot has not “proven AI” in the abstract. It has proven a specific workflow, identified a risk boundary, and provided enough evidence to scale responsibly.
That is operational efficiency with a guardrail. It also supports continuous improvement: the rejected account-change cases become test examples for a future version rather than evidence that the entire project failed.
A Decision Checklist for Leaders
Before approving an AI project, and again before scaling it, ask:
- What specific job changes, and who experiences the change?
- What is the baseline, including quality and waiting time?
- Which benefits are cash, capacity, or risk reduction?
- What must be true for capacity savings to become real value?
- What does the full 12-month cost include?
- Which quality or safety measure would make us pause or roll back?
- How will users correct the system and report failures?
- Who owns the next improvement after launch?
The final question matters because AI ROI is rarely a one-off event. The strongest returns come from a long-term partnership between the business, its users, and the team responsible for improving the system. Start with a measurable workflow, learn from evidence, and extend only where the value remains clear.
Conclusion
AI ROI is not a polished estimate in a pitch deck. It is a disciplined comparison between a real baseline and a changed workflow, with costs, quality, adoption, and risk visible alongside the headline productivity number.
Businesses that measure this way avoid two expensive mistakes: scaling a demonstration that never becomes useful, and abandoning a promising use case because its value was never made visible. They build solutions around users, make operations more efficient, and create a reliable foundation for growth.
If you want to assess an AI opportunity with an honest baseline and a practical path to value, contact Novemind to start the conversation.
Related reading: