Prompt Engineering, Fine-Tuning, or RAG: A Practical Decision Framework
28 September 2026
When an AI pilot produces inconsistent answers, businesses are often offered three answers in quick succession: improve the prompt, fine-tune the model, or build RAG. Each can be useful. Each can also become an expensive detour when selected because it sounds advanced rather than because it solves the actual problem.
The right choice begins with the user outcome. Do people need an assistant to follow a reliable process, answer from changing company information, or express a specialised style at scale? The answer determines the architecture, cost, and long-term maintenance burden. This guide gives decision-makers a practical way to choose, so an AI investment strengthens operational efficiency instead of creating another fragile system.
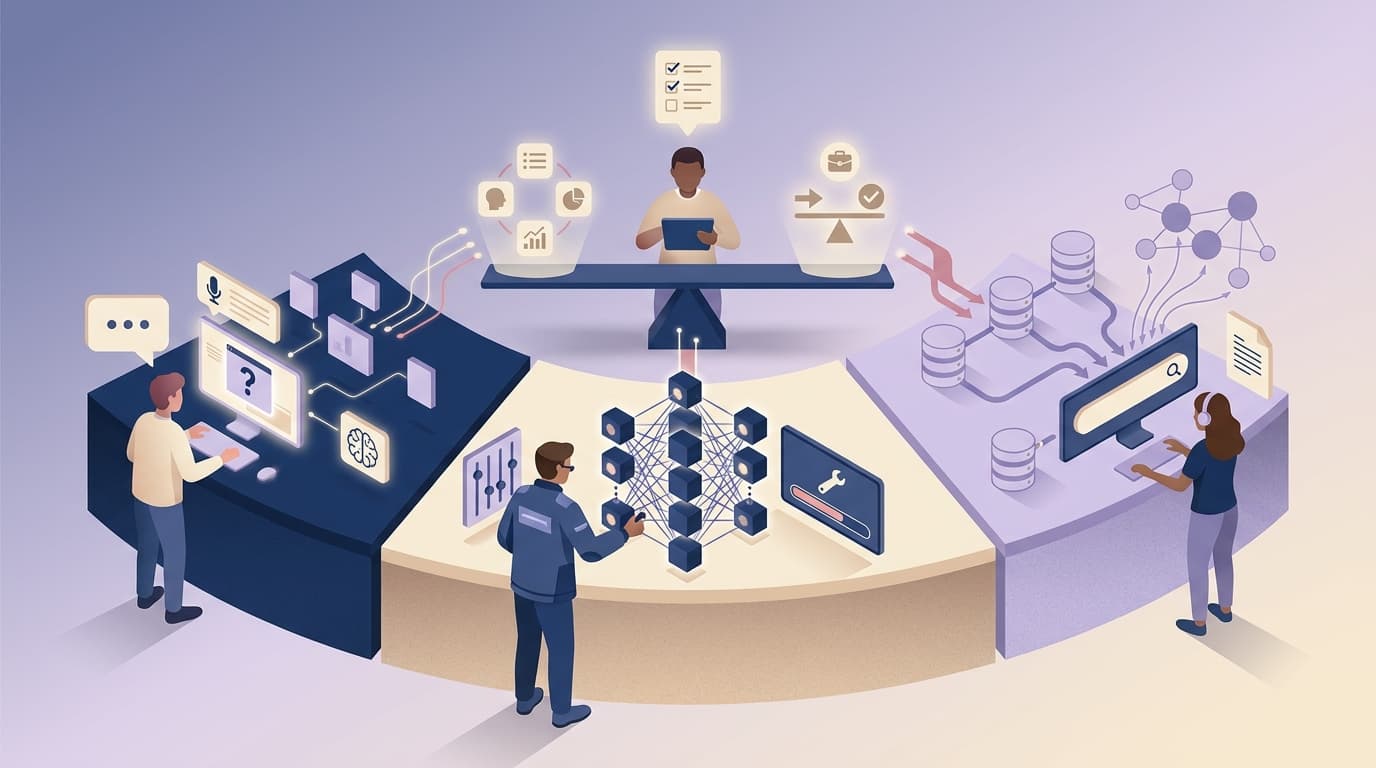
For context on the data-connected option, read our introduction to RAG systems. The short version is that prompts shape behaviour, fine-tuning changes learned patterns, and RAG supplies current, traceable knowledge.
Start with the business problem, not the technique
A model cannot solve ambiguity in the operating process around it. Before choosing a method, define one user group, one workflow, and one measurable success condition. A sales assistant may need accurate product information. A document classifier may need consistent labels. A support tool may need to cite the current policy and hand off complex cases.
Common mistakes include:
- treating company facts as something a model should memorise
- fine-tuning before collecting examples of genuinely good outputs
- using a long prompt to compensate for missing data access or unclear workflow rules
- measuring demos rather than task completion, correction rate, and cost per resolved request
A user-centric design workshop exposes these differences early. It also helps establish whether custom AI is appropriate at all, which is the question explored in build versus buy for business AI. The aim is a robust solution that can evolve with the business, not a one-off model experiment.
Prompt engineering: the best first move for behaviour
Prompt engineering means giving the model clear instructions, examples, output formats, tool rules, and guardrails at request time. It is usually the lowest-cost first intervention because it is fast to change, easy to test, and requires no model-training pipeline.
It works well when the core knowledge is general, the task is bounded, and the problem is primarily consistency. Examples include extracting a fixed set of fields from invoices, drafting first-pass emails in an approved tone, or routing an incoming request to the right team.
A good production prompt is not a clever sentence. It is a versioned instruction set with explicit constraints, realistic examples, structured outputs, and failure behaviour. Test it against real inputs, including difficult cases. Prompt changes should be evaluated like software changes, using the approach in AI evaluation.
Prompt engineering is less suitable when the model must answer from fast-changing internal facts. Repeating thousands of words of policy in every request increases latency and spend, while still leaving version control and citations weak.
RAG: use it when current business knowledge matters
Retrieval-augmented generation, or RAG, retrieves relevant approved content at the moment a user asks a question, then asks the model to answer from that context. It is the appropriate pattern when information changes, users need sources, or permissions control who can see which documents.
Use RAG for product documentation, internal procedures, contracts, knowledge bases, or customer-specific records. Its value is not simply that it can answer more questions. It can make answers traceable and keep the knowledge layer separate from the model provider.
A dependable implementation needs document preparation, access-aware retrieval, source freshness, and monitoring. The architecture choices behind that are covered in building enterprise RAG systems. Start with one bounded corpus and one audience. Track whether retrieved sources were useful, whether answers were grounded, and whether the workflow became faster.
RAG does not replace good instructions. The prompt still tells the model how to use the context, cite sources, and decline when no reliable answer is available. Think of it as a controlled knowledge service feeding a carefully designed assistant.
Fine-tuning: reserve it for repeatable patterns at scale
Fine-tuning trains a model or adapter on many examples so it learns a specialised response pattern. It can reduce prompt length, improve adherence to a narrow format, or make a smaller model perform a repetitive task more effectively. It is not the right mechanism for frequently changing company facts.
Fine-tuning earns consideration when you have a stable task, hundreds or thousands of representative, high-quality examples, and enough volume to justify training and maintenance. A company processing a consistent document type at scale may benefit. A business launching its first internal assistant usually will not.
The hidden cost is not just training. You need data governance, dataset versioning, evaluation against an unchanged holdout set, monitoring for regression, and a retraining plan when the process changes. If examples contain personal or confidential data, governance requirements increase further. The model should not become an uncontrolled archive of information that belongs in a permissioned source system.
Use this decision sequence
Ask these questions in order:
- Is the issue mainly instruction-following or output format? Start with prompt engineering and structured outputs.
- Does the assistant need current, proprietary, or permissioned facts? Add RAG, with source citations and a defined update process.
- Is the task stable, repeated at high volume, and supported by a strong labelled dataset? Evaluate fine-tuning after a prompt and RAG baseline.
- Can you measure success? Track task completion, accuracy, escalation, latency, and euros per useful outcome before expanding.
- Who will own change? Assign an owner for source updates, prompt versions, evaluation, and user feedback.
For many businesses the answer is a combination: a well-tested prompt, RAG for current knowledge, and no fine-tuning until evidence shows a narrow, repeated task warrants it. That sequence protects budget and keeps the architecture portable.
Turn the choice into a practical pilot
Pick a workflow where a better answer saves real time or reduces real risk. Define 30 to 50 representative cases, set a baseline, and release to a small user group. Keep the data and evaluation suite under your control. Review outcomes with the people doing the work, then improve the weakest part of the journey.
The most valuable AI systems are not the ones with the most techniques. They are the ones that fit how people work, provide dependable answers, and improve through continuous support. If you want to choose an approach that respects both your users and your budget, contact Novemind for a practical AI assessment.
Related reading: